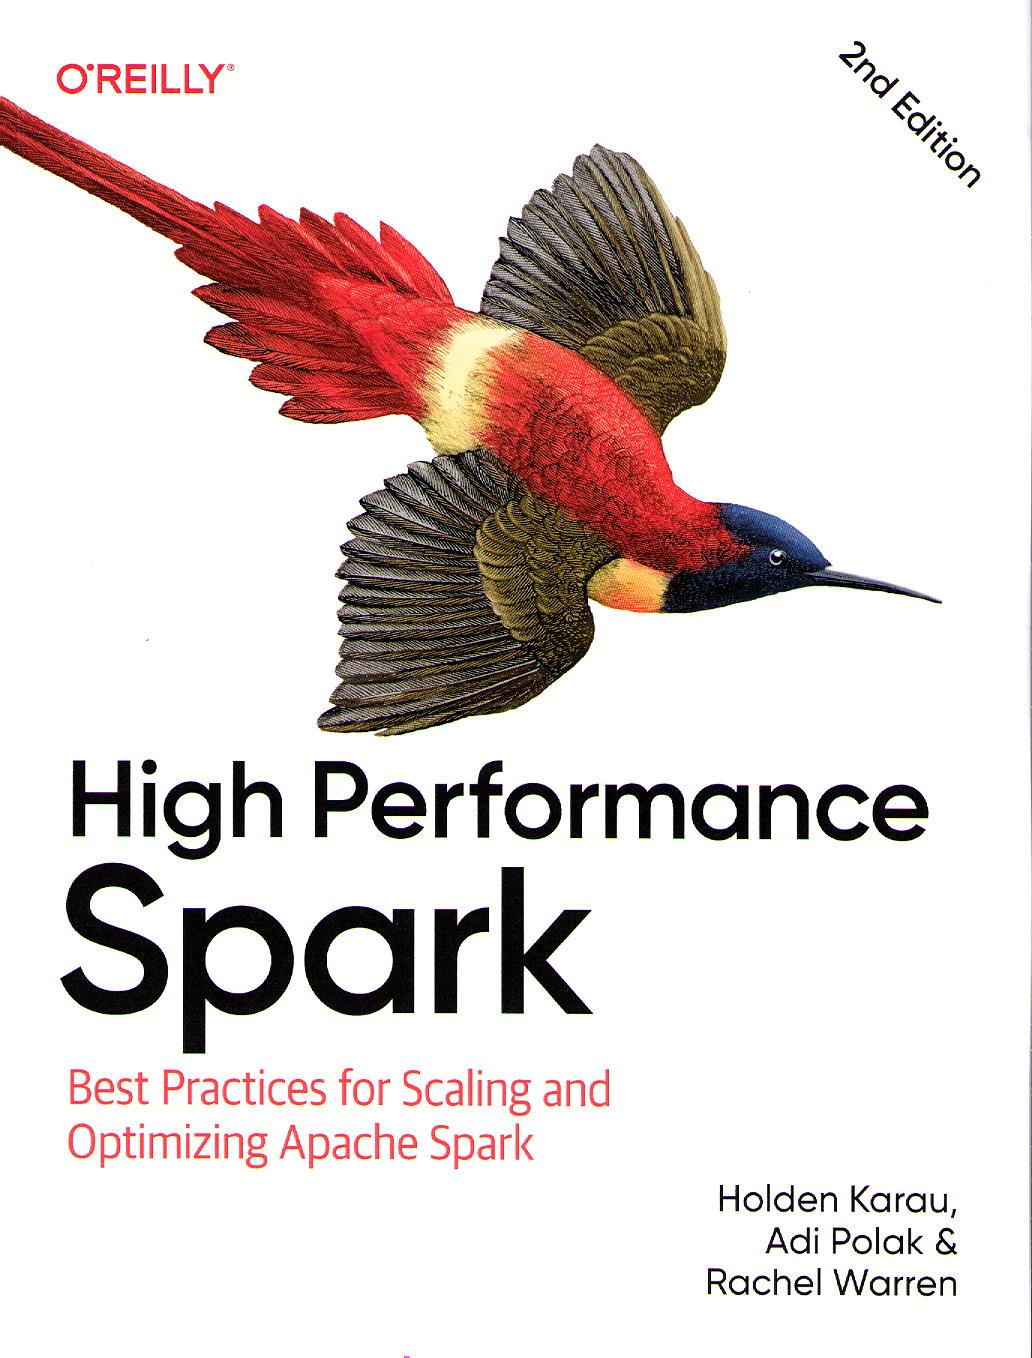
 | | 系統號碼 | 1004115 | | 書刊名 | High performance Spark : best practices for scaling and optimizing apache spark / | | 主要著者 | Karau, Holden, author. | | 其他著者 | Warren, Rachel,;Polak, Adi, | | 出版項 | Sebastopol, CA : O'Reilly Media, Inc., 2026.;Sebastopol, CA : O'Reilly Media, Inc., ©2026 | | 索書號 | QA76.9.D343.K37 2026 | | ISBN | 1098145852 | | 標題 | Spark (Electronic resource : Apache Software Foundation)
Spark (Electronic resource : Apache Software Foundation)-fast
Parallel programs (Computer programs)-Software.
Parallel programs (Computer programs)-Programming. | | | |
|
|
 |
| | 資料類型 | 狀態 | 應還日期 | 預約人數 | 館藏地 | 索書號 | 條碼號 | | 找書 | 圖書 | 在架上 | | 0 | 總館
西文圖書區  | QA76.9.D343 .K37 2026 | W116402 |
| 內容簡介 | Apache Spark is amazing when everything clicks. But if you haven't seen the performance improvements you expected or still don't feel confident enough to use Spark in production, this practical book is for you. Authors Holden Karau, Adi Polak, and Rachel Warren walk you through the secrets of the Spark code base and demonstrate performance optimizations that will help your data pipelines run faster, scale to larger datasets, and avoid costly antipatterns. With this book, you will learn how to accelerate your ML workflows with integrations including PyTorch, handle key skew and take advantage of Spark's new dynamic partitioning, make your code reliable with scalable testing and validation techniques, make Spark high performance, deploy Spark on Kubernetes and similar environments, take advantage of GPU acceleration with RAPIDS and resource profiles, get your Spark jobs to run faster, use Spark to productionize exploratory data science projects, handle even larger datasets with Spark, and gain faster insights by reducing pipeline running times. |
讀者書評 |
尚無書評,
|
|