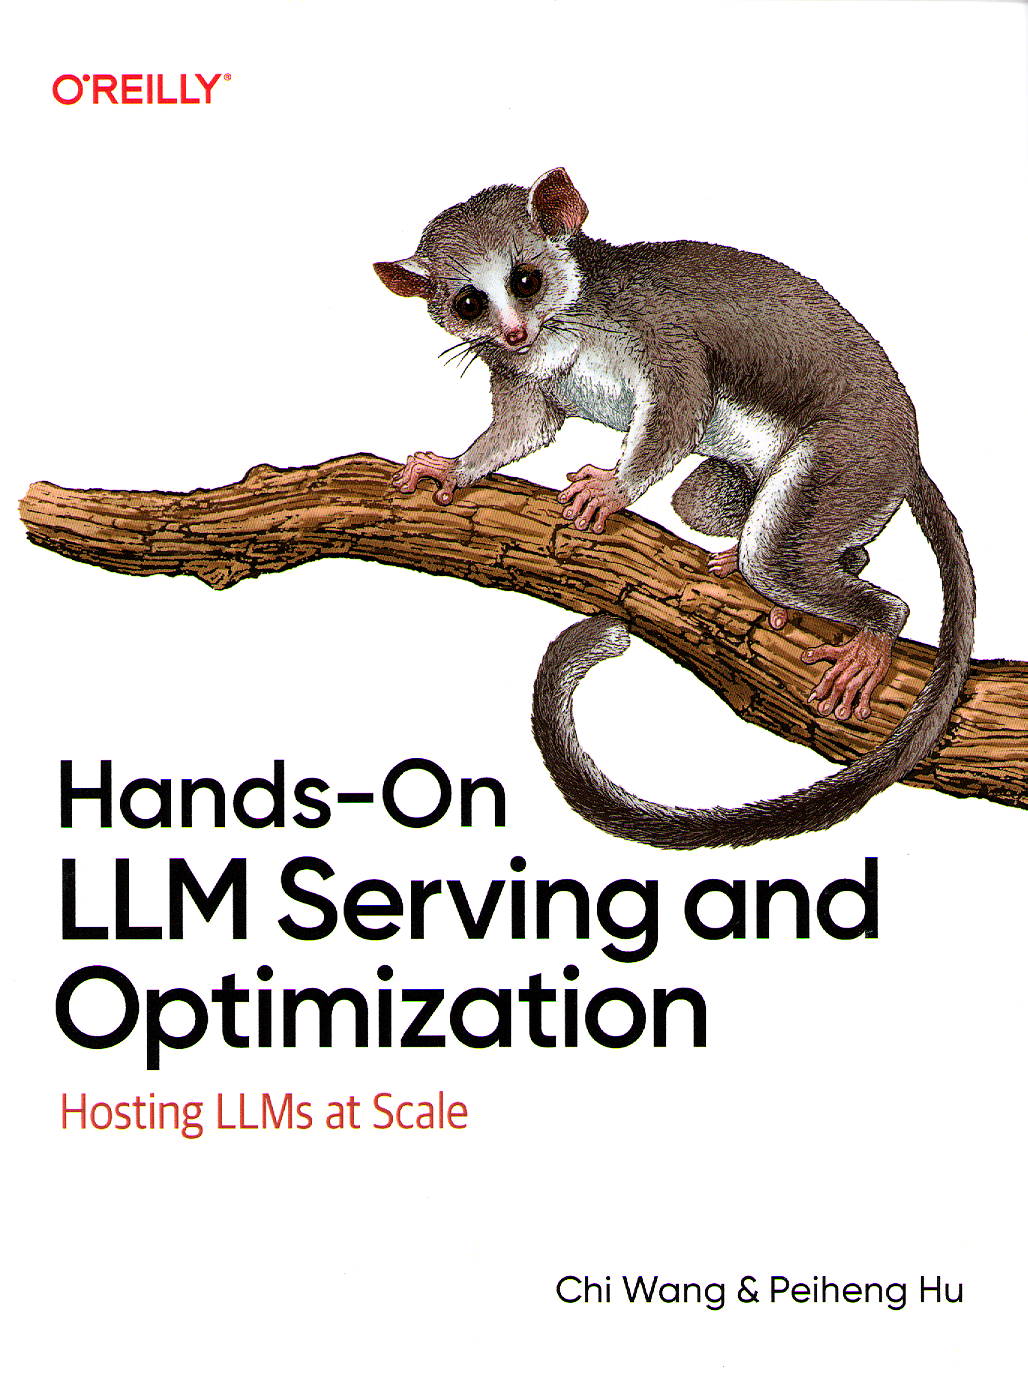
 | | 系統號碼 | 988061 | | 書刊名 | Hands-on LLM serving and optimization : hosting LLMs at scale / | | 主要著者 | Wang, Chi, author. | | 其他著者 | Hu, Peiheng, | | 出版項 | Santa Rosa, CA : O'Reilly Media, Inc., 2026.;Santa Rosa, CA : O'Reilly Media, Inc., ©2026 | | 索書號 | QA76.9.N38.W35 2026 | | ISBN | 9798341621497 | | 標題 | Natural language processing (Computer science)
Artificial intelligence.
Traitement automatique des langues naturelles.
Intelligence artificielle.
artificial intelligence.-aat | | | |
|
|
 |
| | 資料類型 | 狀態 | 應還日期 | 預約人數 | 館藏地 | 索書號 | 條碼號 | | 找書 | 圖書 | 在架上 | | 0 | 總館
西文圖書區  | QA76.9.N38 .W35 2026 | W116358 |
| 內容簡介 | Large language models (LLMs) are rapidly becoming the backbone of AI-driven applications. Without proper optimization, however, LLMs can be expensive to run, slow to serve, and prone to performance bottlenecks. As the demand for real-time AI applications grows, along comes Hands-On Serving and Optimizing LLM Models, a comprehensive guide to the complexities of deploying and optimizing LLMs at scale. In this hands-on book, authors Chi Wang and Peiheng Hu take a real-world approach backed by practical examples and code, and assemble essential strategies for designing robust infrastructures that are equal to the demands of modern AI applications. Whether you're building high-performance AI systems or looking to enhance your knowledge of LLM optimization, this indispensable book will serve as a pillar of your success. Learn the key principles for designing a model-serving system tailored to popular business scenarios Understand the common challenges of hosting LLMs at scale while minimizing costs Pick up practical techniques for optimizing LLM serving performance Build a model-serving system that meets specific business requirements Improve LLM serving throughput and reduce latency Host LLMs in a cost-effective manner, balancing performance and resource efficiency. |
讀者書評 |
尚無書評,
|
|